> ## Documentation Index
> Fetch the complete documentation index at: https://docs.together.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Upload a fine-tuned model
> Serve a fine-tuned model uploaded from your machine, Hugging Face, or S3.
Run inference on your own fine-tuned models by uploading them to Together AI and deploying them for [dedicated model inference](/docs/dedicated-endpoints/overview). You can upload models from your local machine, import them from Hugging Face Hub, or upload from an S3 archive.
Uploads must be fine-tuned variants of a model architecture that Together AI already supports. You can change the weights, but the architecture must match [one of the supported models](/docs/dedicated-endpoints/models) we offer for dedicated inference.
## Requirements
A model is eligible for upload if it meets these requirements:
* **Source:** Your local machine, Hugging Face Hub, or an S3 presigned URL.
* **Architecture:** A fine-tuned variant of a base model that Together AI supports for dedicated inference. See [Available models](/docs/dedicated-endpoints/models) for the list of supported models.
* **Type:** Text generation model.
Meeting these requirements is necessary but not sufficient. Together AI does not accept every model: an unsupported base model, layer type, or adapter rank is rejected with an error identifying the problem at create or upload time.
The model files must be in standard Hugging Face repository format, compatible with `from_pretrained`. A valid model directory contains files like:
```
config.json
generation_config.json
model-00001-of-00004.safetensors
model-00002-of-00004.safetensors
model-00003-of-00004.safetensors
model-00004-of-00004.safetensors
model.safetensors.index.json
special_tokens_map.json
tokenizer.json
tokenizer_config.json
```
### S3 archive requirements
If you're uploading from S3, you must package the files in a single archive (`.zip` or `.tar.gz`) with the model files at the root of the archive. Don't nest them inside an extra top-level directory.
**Correct:** The files are at the root of the archive.
```
config.json
model.safetensors
tokenizer.json
...
```
**Incorrect:** The files are nested inside an extra top-level directory.
```
my-model/
config.json
model.safetensors
tokenizer.json
...
```
To create the archive from within a model directory, run:
```bash Shell theme={null}
cd /path/to/your/model
tar -czvf ../model.tar.gz .
```
The presigned URL must point to the archive file in S3 and have an expiration of at least 100 minutes.
## Create the model
Create the model record in your project before you upload its weights. Creating the record first gives you a model ID for the upload to attach its weights to. Every uploaded model must reference a [supported base model](/docs/dedicated-endpoints/models) via `baseModelId`. An upload can't introduce a new base architecture.
Give the model a readable name (for example `gemma-4-31b-it`), rather than a Hugging Face repo ID.
The base model is referenced by its `baseModelId` (`ml_...`). List the [supported models](/docs/dedicated-endpoints/models) with `tg beta models public --product dedicated` and copy the `baseModelId` of the architecture your fine-tune derives from (for example `ml_CbJNwQC2ZqCU2iFT3mrCh`), or pass a deployment profile's exact `modelName` (for example `Qwen/Qwen3.5-9B-FP8`). Don't use the architecture `id`, which starts with `arch_`:
```bash CLI theme={null}
tg beta models create gemma-4-31b-it \
--base-model ml_CbJNwQC2ZqCU2iFT3mrCh
```
Uploaded models are Private by default, visible only in the project that owns them. Internal visibility makes a model discoverable from every project in your organization. On the [Models](https://api.together.ai/models) page, Internal models from other projects appear under **My models** alongside the selected project's own models. Use the **Visibility** filter (**Internal** or **Private**) to narrow the list. Checking both options matches either scope.
Save the returned model `id` (for example `ml_abc123`). You pass this value to the upload command in the next step. Whether a record holds full weights or a LoRA adapter is fixed when you create it: `create` defaults `--type` to `model`, so a full model needs no type flag. To register a LoRA adapter instead, pass `--type adapter` on create, as described in [Upload a LoRA adapter](/docs/dedicated-endpoints/adapter).
### Create request fields
| Field | Required | Description |
| --------------- | -------- | ------------------------------------------------------------------------------ |
| `name` | Yes | Inference-addressable name for the uploaded model. |
| `base_model_id` | Yes | `baseModelId` (`ml_...`) of the supported base model your weights derive from. |
| `description` | No | Description shown in your project catalog. |
## Upload the model
After creating the model record, upload its weights. Use a local upload when the files are on your machine, or a remote upload to stream them from Hugging Face or a presigned S3 URL. Pass the model `id` you saved in the previous step.
### Upload from your machine
Point the CLI at your local model directory. The CLI handles the multipart upload for you:
```bash CLI theme={null}
tg beta models upload ml_abc123 ./path/to/model-dir
```
### Upload from Hugging Face or S3
A remote upload streams the weights server-side, so you don't download them locally first. Pass the source URL as `--from` (use `--token` for gated or private Hugging Face repos). For S3, pass the presigned archive URL as `--from` (no token needed):
```bash CLI theme={null}
tg beta models remote-uploads create ml_abc123 \
--from https://huggingface.co/your-org/your-repo \
--token hf_your_token
```
The response is the upload job object, with `id`, `modelId`, and `status` at the top level:
```json theme={null}
{
"id": "job_abc123",
"projectId": "proj_abc123",
"modelId": "ml_abc123",
"remoteUrl": "https://huggingface.co/your-org/your-repo",
"status": "REMOTE_UPLOAD_STATUS_PENDING",
"statusMessage": "",
"restartCount": 0,
"maxRestarts": 0,
"createdAt": "2026-07-02T20:00:00Z",
"updatedAt": "2026-07-02T20:00:00Z"
}
```
Save the job `id`. You use it to poll for upload status.
### Upload from the console
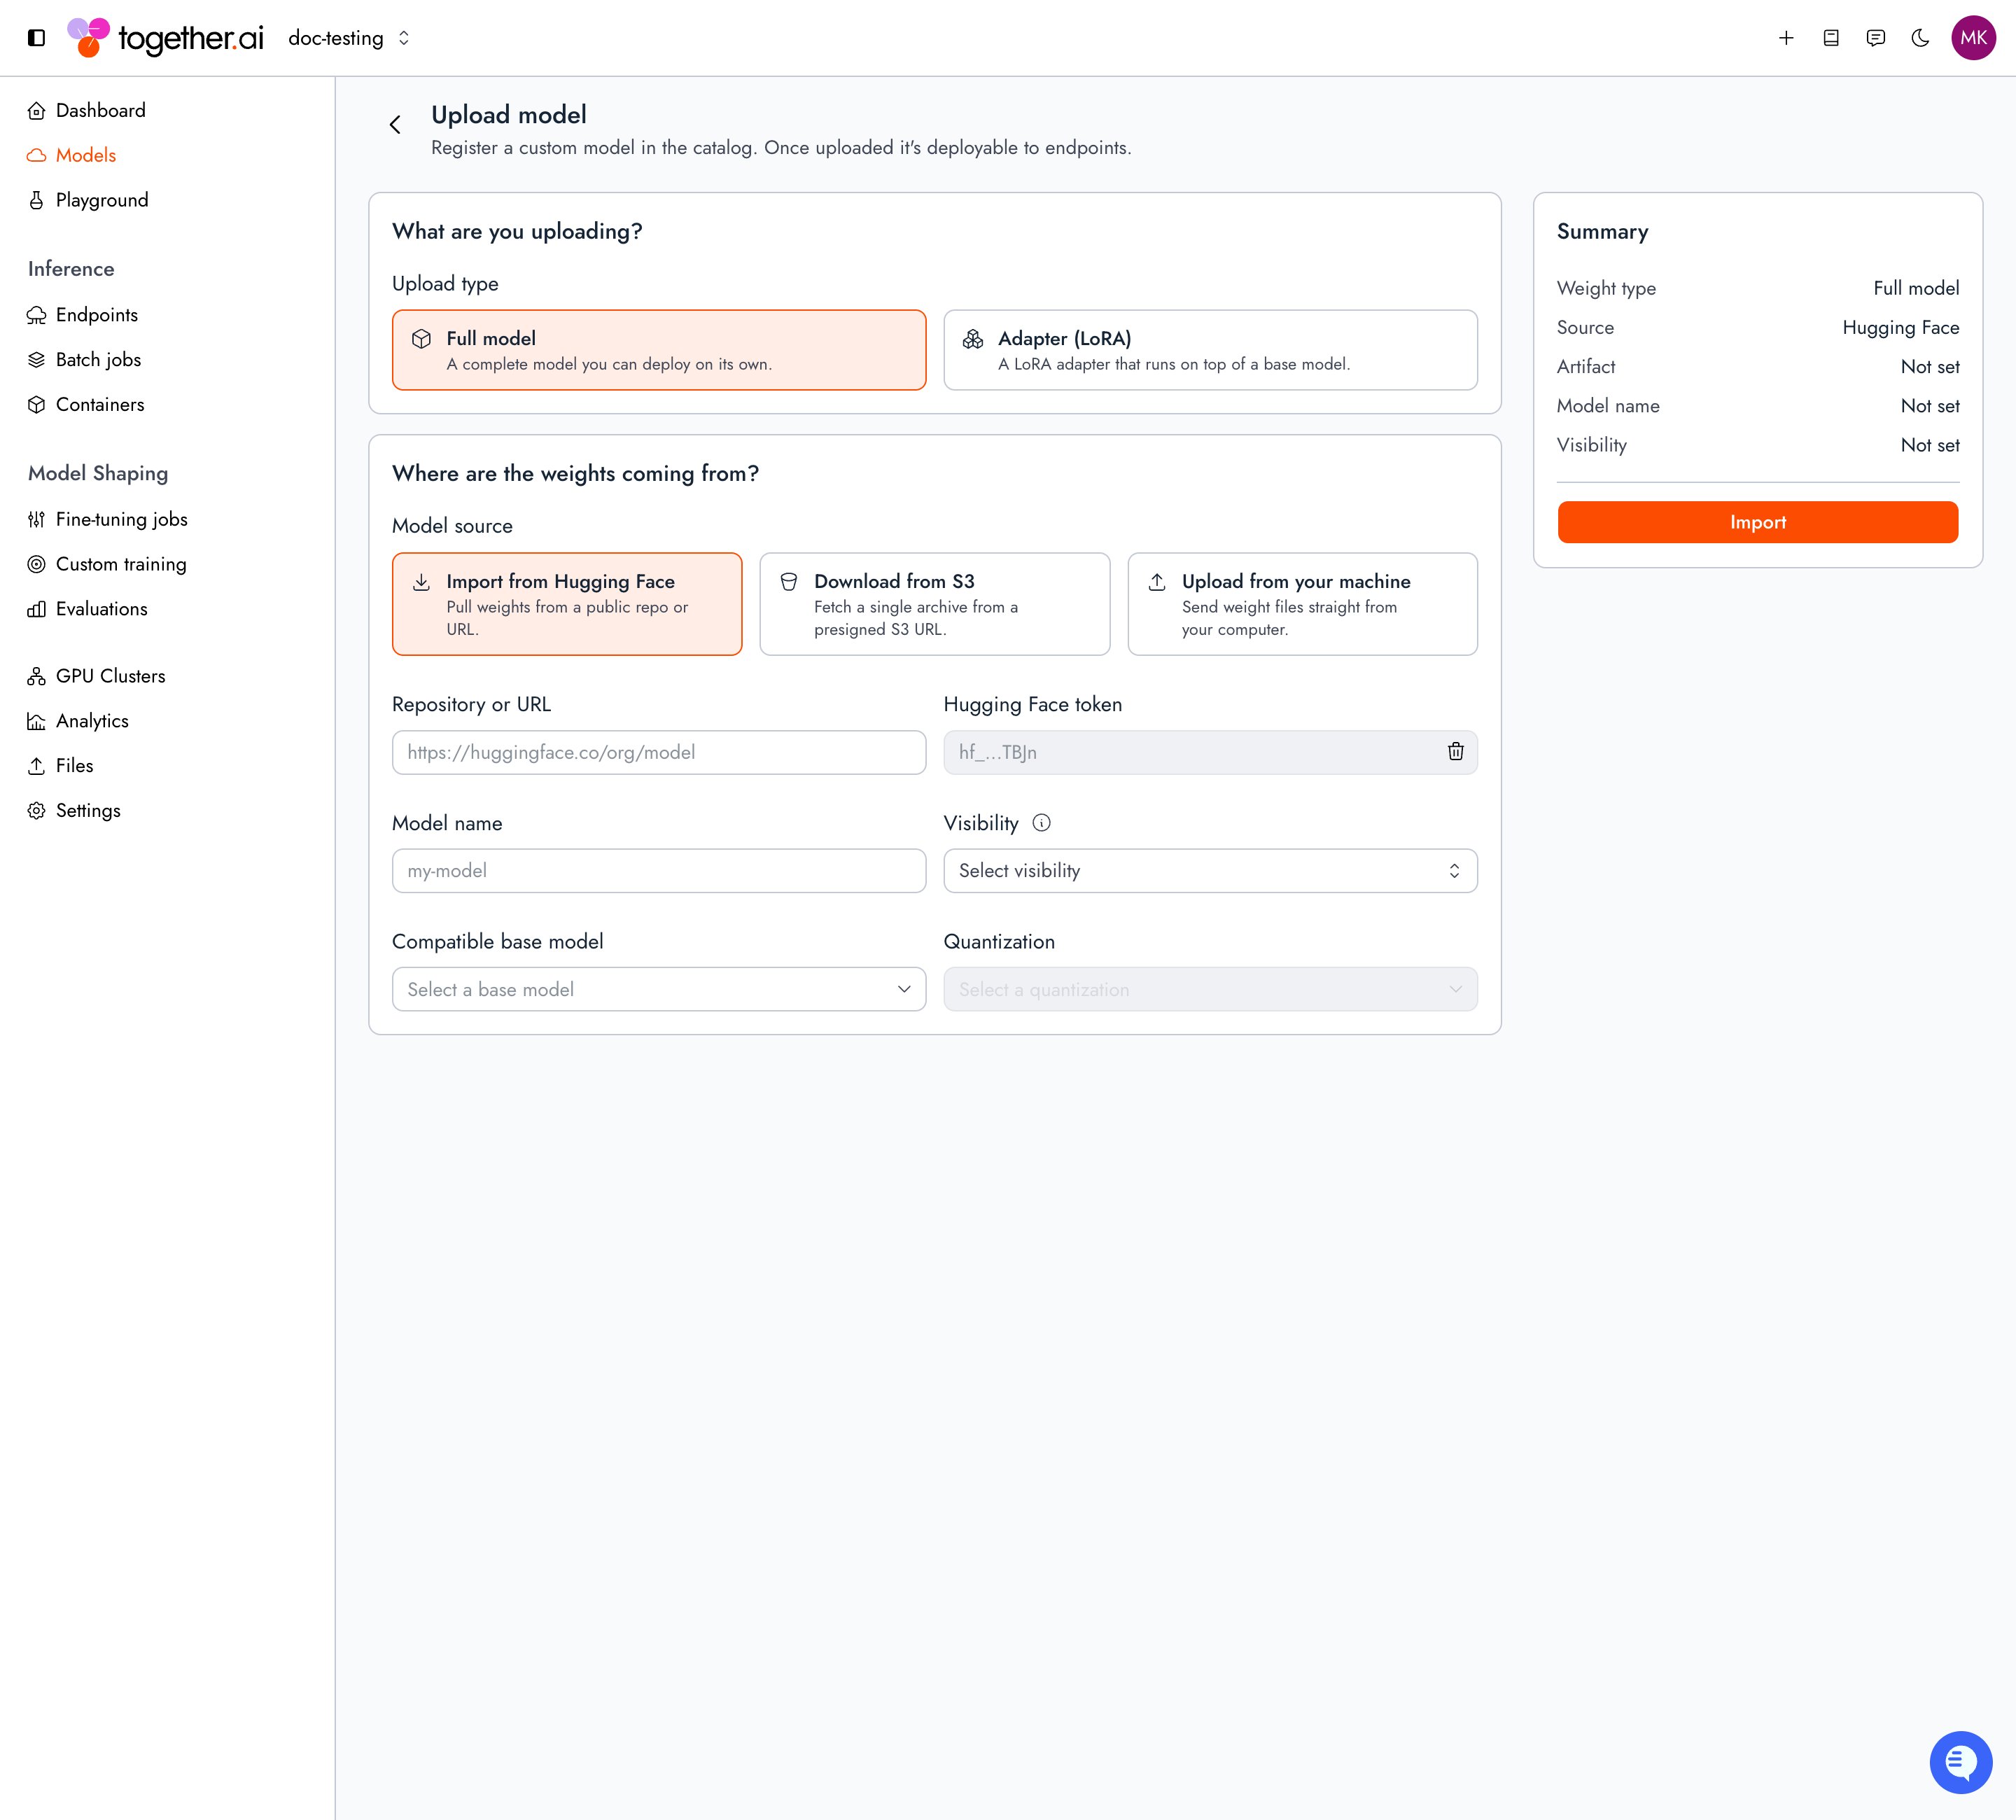
The console combines creating the model record and uploading its weights into a single form. Go to [Models > Upload a model](https://api.together.ai/models/upload).
Leave **Upload type** set to **Full model**.
Under **Model source**, select **Import from Hugging Face** and enter the repo path or URL (add a **Hugging Face token** for gated or private repos), or select **Download from S3** and paste a presigned archive URL. **Upload from your machine** shows a CLI command instead: the browser can't upload local weights, so use [`tg beta models upload`](#upload-from-your-machine) for files on your machine.
Enter a **Model name**, choose a **Visibility**, and complete the **Compatible base model** and **Quantization** fields.
Select **Import**. The upload runs server-side, with progress shown below the form. You can leave the form: the model appears under **My models** with an **Uploading** badge while the job is pending or running.
 ## Check upload status
Poll the remote-upload job until `status` is `REMOTE_UPLOAD_STATUS_SUCCEEDED`. The model is ready to deploy at that point.
```bash CLI theme={null}
# One upload job
tg beta models remote-uploads retrieve job_abc123
# All upload jobs in the project
tg beta models remote-uploads list
```
Once the job reaches `REMOTE_UPLOAD_STATUS_SUCCEEDED`, confirm the files landed:
```bash CLI theme={null}
tg beta models ls-files ml_abc123
```
You can also track uploads on the [My models](https://api.together.ai/models?category=my-models) page in the dashboard. While a remote upload is pending or running, the model floats to the top of **My models** with an **Uploading** badge. Open the model to watch the live **Upload progress** event log on the model detail page. The revisions table appears after the upload finishes. That list also includes Internal-visibility models from other projects in your organization. Use the **Visibility** filter to show only **Internal** or only **Private** models.
## Check revision validation
After files land, Together validates the revision's weights automatically. Validation checks that the weights are in safetensors format and that the config and architecture are compatible with the base model. A revision must reach `REVISION_VALIDATION_STATUS_SUCCESS` before you can deploy it when you pin that revision explicitly.
List revisions for a model:
```bash CLI theme={null}
tg beta models ls-revisions ml_abc123
```
The list and retrieve revision APIs also return validation fields on each revision. Replace `$PROJECT_ID` with your project ID (`proj_...`):
```bash Shell theme={null}
# All revisions
curl -s -H "Authorization: Bearer $TOGETHER_API_KEY" \
"https://api.together.ai/v2/projects/$PROJECT_ID/models/ml_abc123/revisions"
# One revision
curl -s -H "Authorization: Bearer $TOGETHER_API_KEY" \
"https://api.together.ai/v2/projects/$PROJECT_ID/models/ml_abc123/revisions/rv_abc123"
```
Each revision in the response includes:
```json theme={null}
{
"data": [
{
"revisionId": "rv_abc123",
"createdAt": "2026-07-02T20:05:00Z",
"validationStatus": "REVISION_VALIDATION_STATUS_SUCCESS",
"lastValidatedAt": "2026-07-02T20:06:00Z",
"validationErrors": []
}
],
"object": "list"
}
```
### Revision validation fields
| Field | Description |
| ------------------ | ----------------------------------------------------------------------------------------- |
| `validationStatus` | Validation state for this revision. See the table below. |
| `lastValidatedAt` | When validation last ran for this revision. Omitted until validation has started. |
| `validationErrors` | Errors from the last validation run. Empty when validation succeeded or is still pending. |
### `validationStatus` values
| Value | Meaning |
| ---------------------------------------- | --------------------------------------------------------------------------------------- |
| `REVISION_VALIDATION_STATUS_PENDING` | Validation is queued or running. Poll until the status changes. |
| `REVISION_VALIDATION_STATUS_SUCCESS` | Weights validated successfully. The revision is ready to deploy. |
| `REVISION_VALIDATION_STATUS_FAILED` | Validation failed. Read `validationErrors` for the cause. |
| `REVISION_VALIDATION_STATUS_ERROR` | Validation could not complete due to an internal error. Retry later or contact support. |
| `REVISION_VALIDATION_STATUS_UNSPECIFIED` | Validation has not started yet. |
When validation fails, each entry in `validationErrors` includes `rule`, `severity`, and `message` describing what went wrong. Common causes include missing safetensors files, an invalid `config.json`, or weights that don't match the declared base model.
Only safetensors format is supported. Models with only `.bin` or `.pt` files fail validation.
## Deploy the model
Once the upload completes, your model has an ID (`ml_...`) in your project. Deploy it the same way as a base model. First, find its ID by listing the models in your project:
```bash CLI theme={null}
tg beta models list
```
Then deploy it. The CLI's `deploy` command creates the endpoint, attaches a deployment bound to your uploaded model and a [config](/docs/dedicated-endpoints/configs), and routes all traffic to it in one step:
```bash CLI theme={null}
tg beta endpoints deploy ml_abc123 \
--endpoint my-custom-model \
--config cr_CbzGdmn14t3HYrXXitmKa
```
Once the deployment is ready, send a request to the endpoint string, as shown in the [quickstart](/docs/dedicated-endpoints/quickstart#step-2-send-a-request). See [Manage deployments](/docs/dedicated-endpoints/manage) for the individual lifecycle operations.
## Troubleshooting
**"Model not found" during upload:** Create the model record first with `tg beta models create`, and pass the returned `id` to the upload command.
**`base_model_id is required` on create:** Every uploaded model must reference a supported base model. List [supported models](/docs/dedicated-endpoints/models) and set `--base-model` to the matching `baseModelId` (`ml_...`), not the architecture `id` (`arch_...`).
**`tokenizer.chat_template is not set` during chat inference:** The uploaded tokenizer doesn't define a chat template. Add a compatible `chat_template` to `tokenizer_config.json` before uploading, or use the text completions API with the prompt format expected by the model.
**Model delete fails with `the model is referenced by a live deployment` (HTTP 400):** A deployment still references this model. [Stop the deployment](/docs/dedicated-endpoints/manage#stop-a-deployment), wait for `DEPLOYMENT_STATE_STOPPED`, [delete the deployment](/docs/dedicated-endpoints/manage#delete-resources), then delete the model with `tg beta models delete `.
**Revision validation failed or still pending:** Check `validationStatus` on the revision with [Check revision validation](#check-revision-validation). Wait for `REVISION_VALIDATION_STATUS_SUCCESS` before you deploy a pinned revision.