> ## Documentation Index
> Fetch the complete documentation index at: https://docs.together.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Visualize endpoint metrics in Grafana
> Scrape the metrics endpoint with Prometheus and import the example Grafana dashboard for dedicated endpoints.
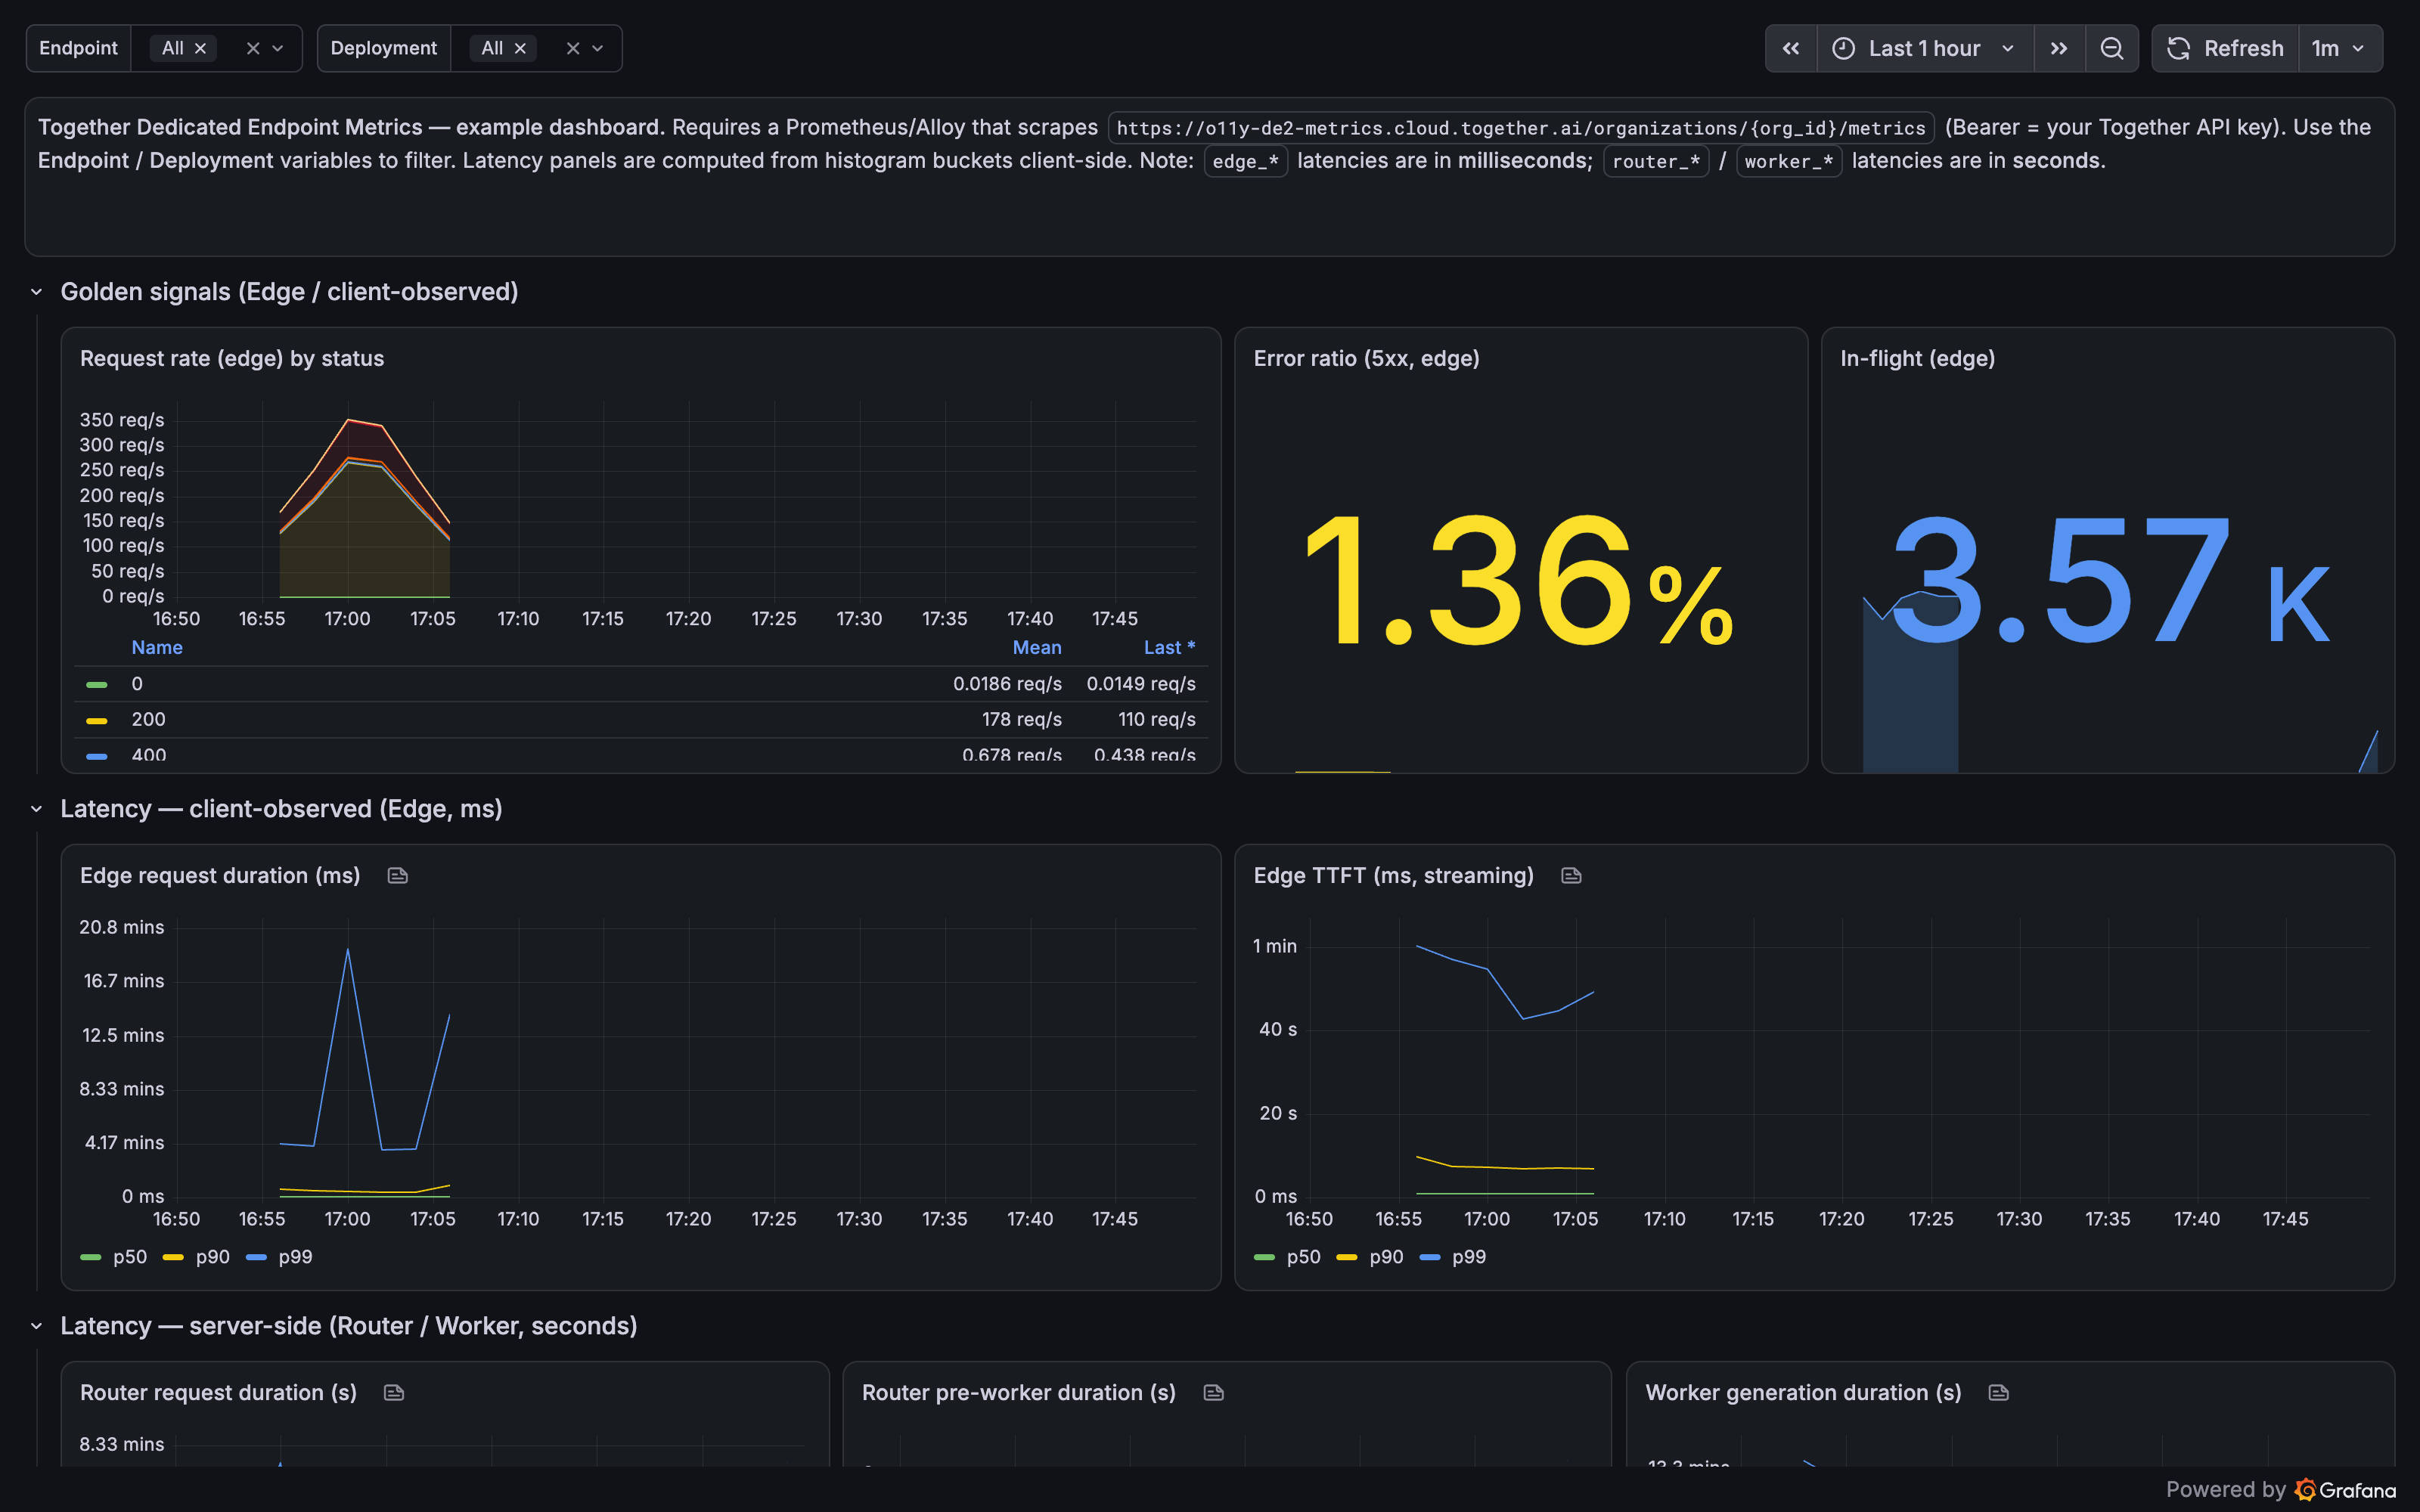
Learn how to set up a Grafana dashboard for your dedicated endpoints to visualize endpoint request rates and error ratios, client-observed and server-side latency percentiles, token throughput, and engine cache utilization, filterable by endpoint and deployment.
The dashboard you'll create in this guide runs Prometheus and Grafana locally with Docker Compose, scrapes the [Prometheus-compatible metrics endpoint](/docs/dedicated-endpoints/monitoring#prometheus-compatible-metrics-endpoint), and imports an example dashboard. The same dashboard works with any Prometheus-compatible stack.
 The metrics endpoint is in beta. The host and path are subject to change, and access may need to be enabled for your organization. Confirm availability with your Together AI contact before you build against it.
## Requirements
* A [Together AI API key](https://api.together.ai/settings/api-keys) set as `TOGETHER_API_KEY` in your terminal.
* The [Together CLI](/docs/dedicated-endpoints/quickstart#requirements) installed.
* [Docker](https://docs.docker.com/get-docker/) with the Compose plugin.
* A dedicated endpoint serving traffic. The next section creates one if you don't have one already.
## Step 1: Deploy an endpoint and send traffic
The dashboard only shows data for endpoints that are serving requests. If you already have a dedicated endpoint taking traffic, skip to [Find your organization ID](#find-your-organization-id).
Deploy a small model on its default hardware:
```bash theme={null}
tg beta endpoints deploy google/gemma-4-E4B-it \
--endpoint grafana-demo
```
Check its status with `tg beta endpoints get`, passing the deployment ID from the deploy output. Once the deployment reaches `DEPLOYMENT_STATE_READY`, send it a steady trickle of requests so every panel has data. Leave this loop running while you set up Grafana:
```bash theme={null}
while true; do
curl -s https://api-inference.together.ai/v1/chat/completions \
-H "Authorization: Bearer $TOGETHER_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "your_project_slug/grafana-demo",
"messages": [{"role": "user", "content": "Write a haiku about dashboards."}],
"stream": true
}' > /dev/null
sleep 5
done
```
Replace `your_project_slug/grafana-demo` with the endpoint string from the deploy output. Keep `"stream": true` in the request body, because the time-to-first-token panels only count streaming requests. See the [quickstart](/docs/dedicated-endpoints/quickstart) for the full deploy walkthrough.
## Step 2: Find your organization ID
The metrics endpoint is scoped to your organization, so the scrape path needs your organization ID. Print it with the CLI:
```bash theme={null}
tg whoami
```
```text theme={null}
Project: My Project (proj_abc123)
Organization: My Organization (org_abc123)
```
Copy the `org_` value. Then confirm the metrics endpoint responds for your organization:
```bash theme={null}
curl -H "Authorization: Bearer $TOGETHER_API_KEY" \
"https://o11y-de2-metrics.cloud.together.ai/organizations/org_abc123/metrics"
```
The response is a plain-text Prometheus exposition: `# TYPE` lines followed by series like `edge_inference_requests_total{endpoint_id="ep_...",status_code="200"}`. An empty response means no dedicated endpoint in the organization has served traffic recently.
## Step 3: Run Prometheus and Grafana
Create a directory with three files: a Compose file, a Prometheus scrape config, and a Grafana data source definition.
`docker-compose.yml` runs the two services:
```yaml docker-compose.yml theme={null}
services:
prometheus:
image: prom/prometheus:latest
volumes:
- ./prometheus.yml:/etc/prometheus/prometheus.yml
ports:
- "9090:9090"
grafana:
image: grafana/grafana:latest
volumes:
- ./grafana-datasource.yml:/etc/grafana/provisioning/datasources/together.yml
ports:
- "3000:3000"
depends_on:
- prometheus
```
`prometheus.yml` scrapes the metrics endpoint once a minute. Fill in your API key and organization ID:
```yaml prometheus.yml theme={null}
global:
scrape_interval: 60s
scrape_timeout: 55s
scrape_configs:
- job_name: together-endpoint-metrics
scheme: https
authorization:
credentials: your_together_api_key
metrics_path: /organizations/your_org_id/metrics
static_configs:
- targets: ["o11y-de2-metrics.cloud.together.ai"]
```
`grafana-datasource.yml` pre-configures Grafana with Prometheus as its data source, so the dashboard import can bind to it directly:
```yaml grafana-datasource.yml theme={null}
apiVersion: 1
datasources:
- name: Prometheus
type: prometheus
access: proxy
url: http://prometheus:9090
isDefault: true
jsonData:
timeInterval: 60s
```
The `timeInterval` value must match the `scrape_interval` in `prometheus.yml`. Grafana uses it to size rate windows, and without it every rate and percentile panel on the dashboard stays empty because Grafana assumes the default 15-second scrape interval.
Start the stack:
```bash theme={null}
docker compose up -d
```
Open the Prometheus targets page at [http://localhost:9090/targets](http://localhost:9090/targets) and confirm the `together-endpoint-metrics` target reports **UP**. The target stays in an unknown state until the first scrape completes, usually within a minute.
The scrape config contains your API key in plain text. Keep the directory out of version control, or move the key into a file referenced by `credentials_file` instead of `credentials`.
## Step 4: Import the dashboard
Together AI publishes an example dashboard for these metrics in the [together-cookbook](https://github.com/togethercomputer/together-cookbook/tree/main/third_party_integrations/Grafana_Dedicated_Endpoints) repository. It requires Grafana 10.2 or later and works with any Prometheus data source, including the local stack above.
1. Download the dashboard JSON:
```bash theme={null}
curl -O https://raw.githubusercontent.com/togethercomputer/together-cookbook/main/third_party_integrations/Grafana_Dedicated_Endpoints/together-dedicated-endpoints-dashboard.json
```
2. Open Grafana at [http://localhost:3000](http://localhost:3000) and sign in. The default credentials are `admin` / `admin`.
3. Go to **Dashboards**, select **New**, then **Import**.
4. Upload `together-dedicated-endpoints-dashboard.json`, select the **Prometheus** data source when prompted, and select **Import**.
The dashboard loads with the **Endpoint** and **Deployment** variables at the top set to **All**. Use them to focus on a single endpoint, or on one deployment during an [A/B test](/docs/dedicated-endpoints/ab-tests) or [traffic split](/docs/dedicated-endpoints/split-traffic).
Panels populate as Prometheus accumulates scrapes. Rate and percentile panels need at least two scrapes, so expect the dashboard to fill in over the first few minutes.
## Step 5: Read the dashboard
The rows follow the request path from the client inward, matching the [metric groups](/docs/dedicated-endpoints/monitoring#available-metrics) on the monitoring page:
* **Golden signals (edge):** Request rate stacked by status code, the 5xx error ratio, and in-flight requests, all measured at the front-door proxy. This row is the client's view of the endpoint and the first place to look during an incident.
* **Latency, client-observed (edge):** Request duration and time to first token as p50, p90, and p99, computed in Grafana from histogram buckets. Edge latencies are in milliseconds.
* **Latency, server-side (router and worker):** Request duration at the router, pre-worker routing and queue overhead, and generation duration, time to first token, and time per output token at the worker. Router and worker latencies are in seconds, not milliseconds. A gap between edge latency and worker latency points at network or queueing overhead rather than model speed.
* **Throughput and tokens:** Request rate compared across the edge, router, and worker layers, token throughput by token type, and tokens per request. The layer comparison shows where requests drop when the layers disagree.
* **Engine and cache (worker):** KV cache utilization per deployment and the prefix cache hit rate. Sustained high KV cache utilization is a signal to [scale up or out](/docs/dedicated-endpoints/scaling), and a low hit rate means little prefix reuse across requests.
The metrics endpoint exposes raw counters, gauges, and histogram buckets only. Every rate, ratio, and percentile on the dashboard is computed by Grafana with PromQL, so you can copy any panel's query as a starting point for your own panels or alert rules.
Congrats! You've set up a Grafana dashboard for your dedicated endpoints.
## Use a hosted Grafana instance
The same dashboard works in Grafana Cloud or any other hosted Grafana instance. Point a Prometheus-compatible collector, such as Grafana Alloy or a Prometheus instance with `remote_write`, at the metrics endpoint with the same scheme, path, and bearer credentials as the `prometheus.yml` above, then import the dashboard JSON against the data source that collector writes to.
## Troubleshooting
* **The Prometheus target shows a timeout or context deadline error:** Organizations with many endpoints can take longer than the default timeout to scrape. Raise `scrape_interval` and `scrape_timeout` together, for example to `120s` and `115s`.
* **The scrape returns 401:** The API key must belong to the organization in the scrape path. Check both against `tg whoami`.
* **Panels are empty:** Confirm the endpoint is serving requests, the Prometheus target is **UP**, and the dashboard time range covers the last few minutes. Rate panels stay empty until two scrapes have completed.
* **Time-to-first-token panels are empty but others populate:** The edge TTFT panel only counts streaming requests. Send requests with `"stream": true`.
* **The Router TTFT panel is empty:** This series depends on a newer router build. The panel fills in as the rollout completes, and the worker TTFT panel covers the same question in the meantime.
## Next steps
The full metric and label tables behind the dashboard.
Act on what the dashboard shows by tuning replica scaling.