> ## Documentation Index
> Fetch the complete documentation index at: https://docs.together.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Quickstart
> Deploy a model on dedicated hardware in a few minutes.
Follow this guide to deploy a model for dedicated inference, send it a request, and scale it down when you're done.
## Requirements
Before you begin, make sure you have:
* [Created an account](https://api.together.ai/settings/projects/~first/api-keys) and generated an API key.
* [Set your API key as an environment variable](/docs/api-keys-authentication#set-as-an-environment-variable) in your terminal.
* Installed the Together CLI:
```bash theme={null}
# Install
uv tool install "together[cli]"
# Upgrade
uv tool upgrade "together[cli]"
# List commands
tg --help
```
The dedicated model inference commands require Together CLI version `2.24.0` or later. Check your version with `tg --version`.
In CI, agents, or other environments where the CLI cannot prompt for confirmation, select a project before deploying. Run `tg whoami` to find your project ID, then set `TOGETHER_PROJECT_ID` or pass `--project ` to the command.
## Step 1: Deploy a model
Deploy `google/gemma-4-E4B-it`, one of the [supported models](/docs/dedicated-endpoints/models) Together hosts. The deployment provisions in the background: for a model this size, first-time provisioning usually takes about 5 to 10 minutes while the weights download and hardware is allocated, and larger models take longer.
The `endpoints deploy` command creates an endpoint, attaches a deployment on the model's default hardware, and routes all traffic to it:
```bash theme={null}
tg beta endpoints deploy google/gemma-4-E4B-it \
--endpoint quickstart-endpoint
```
The command returns as soon as the resources are created and prints the endpoint's details:
```bash theme={null}
√ Model deployed to endpoint your-project-slug/quickstart-endpoint.
╭─ Endpoint Details for quickstart-endpoint ───────────────────────────────────╮
│ Endpoint string your-project-slug/quickstart-endpoint │
│ Endpoint ID ep_abc123 │
│ Created at 07/13/2026, 06:52 PM │
│ Updated at 07/13/2026, 06:52 PM │
│ Visibility Private │
│ Web URL https://api.together.ai/endpoints/ep_abc123 │
╰──────────────────────────────────────────────────────────────────────────────╯
Deployments
╭──────────────────────────────────────┬───────────────────┬───────────────────╮
│ Deployment │ Model │ │
├──────────────────────────────────────┼───────────────────┼───────────────────┤
│ Name: │ google/gemma-4… │ Status: │
│ google-gemma-4-E4B-it-BF16-abc123… │ │ Provisioning │
│ ID: dep_abc123 │ │ Replicas: 0 / 1 │
╰──────────────────────────────────────┴───────────────────┴───────────────────╯
```
Note the **endpoint string** (`your-project-slug/quickstart-endpoint`): pass it as the `model` parameter when you send requests.
Check the deployment's status with the deployment ID from the output, and wait for `DEPLOYMENT_STATE_READY`:
```bash theme={null}
tg beta endpoints get dep_abc123
```
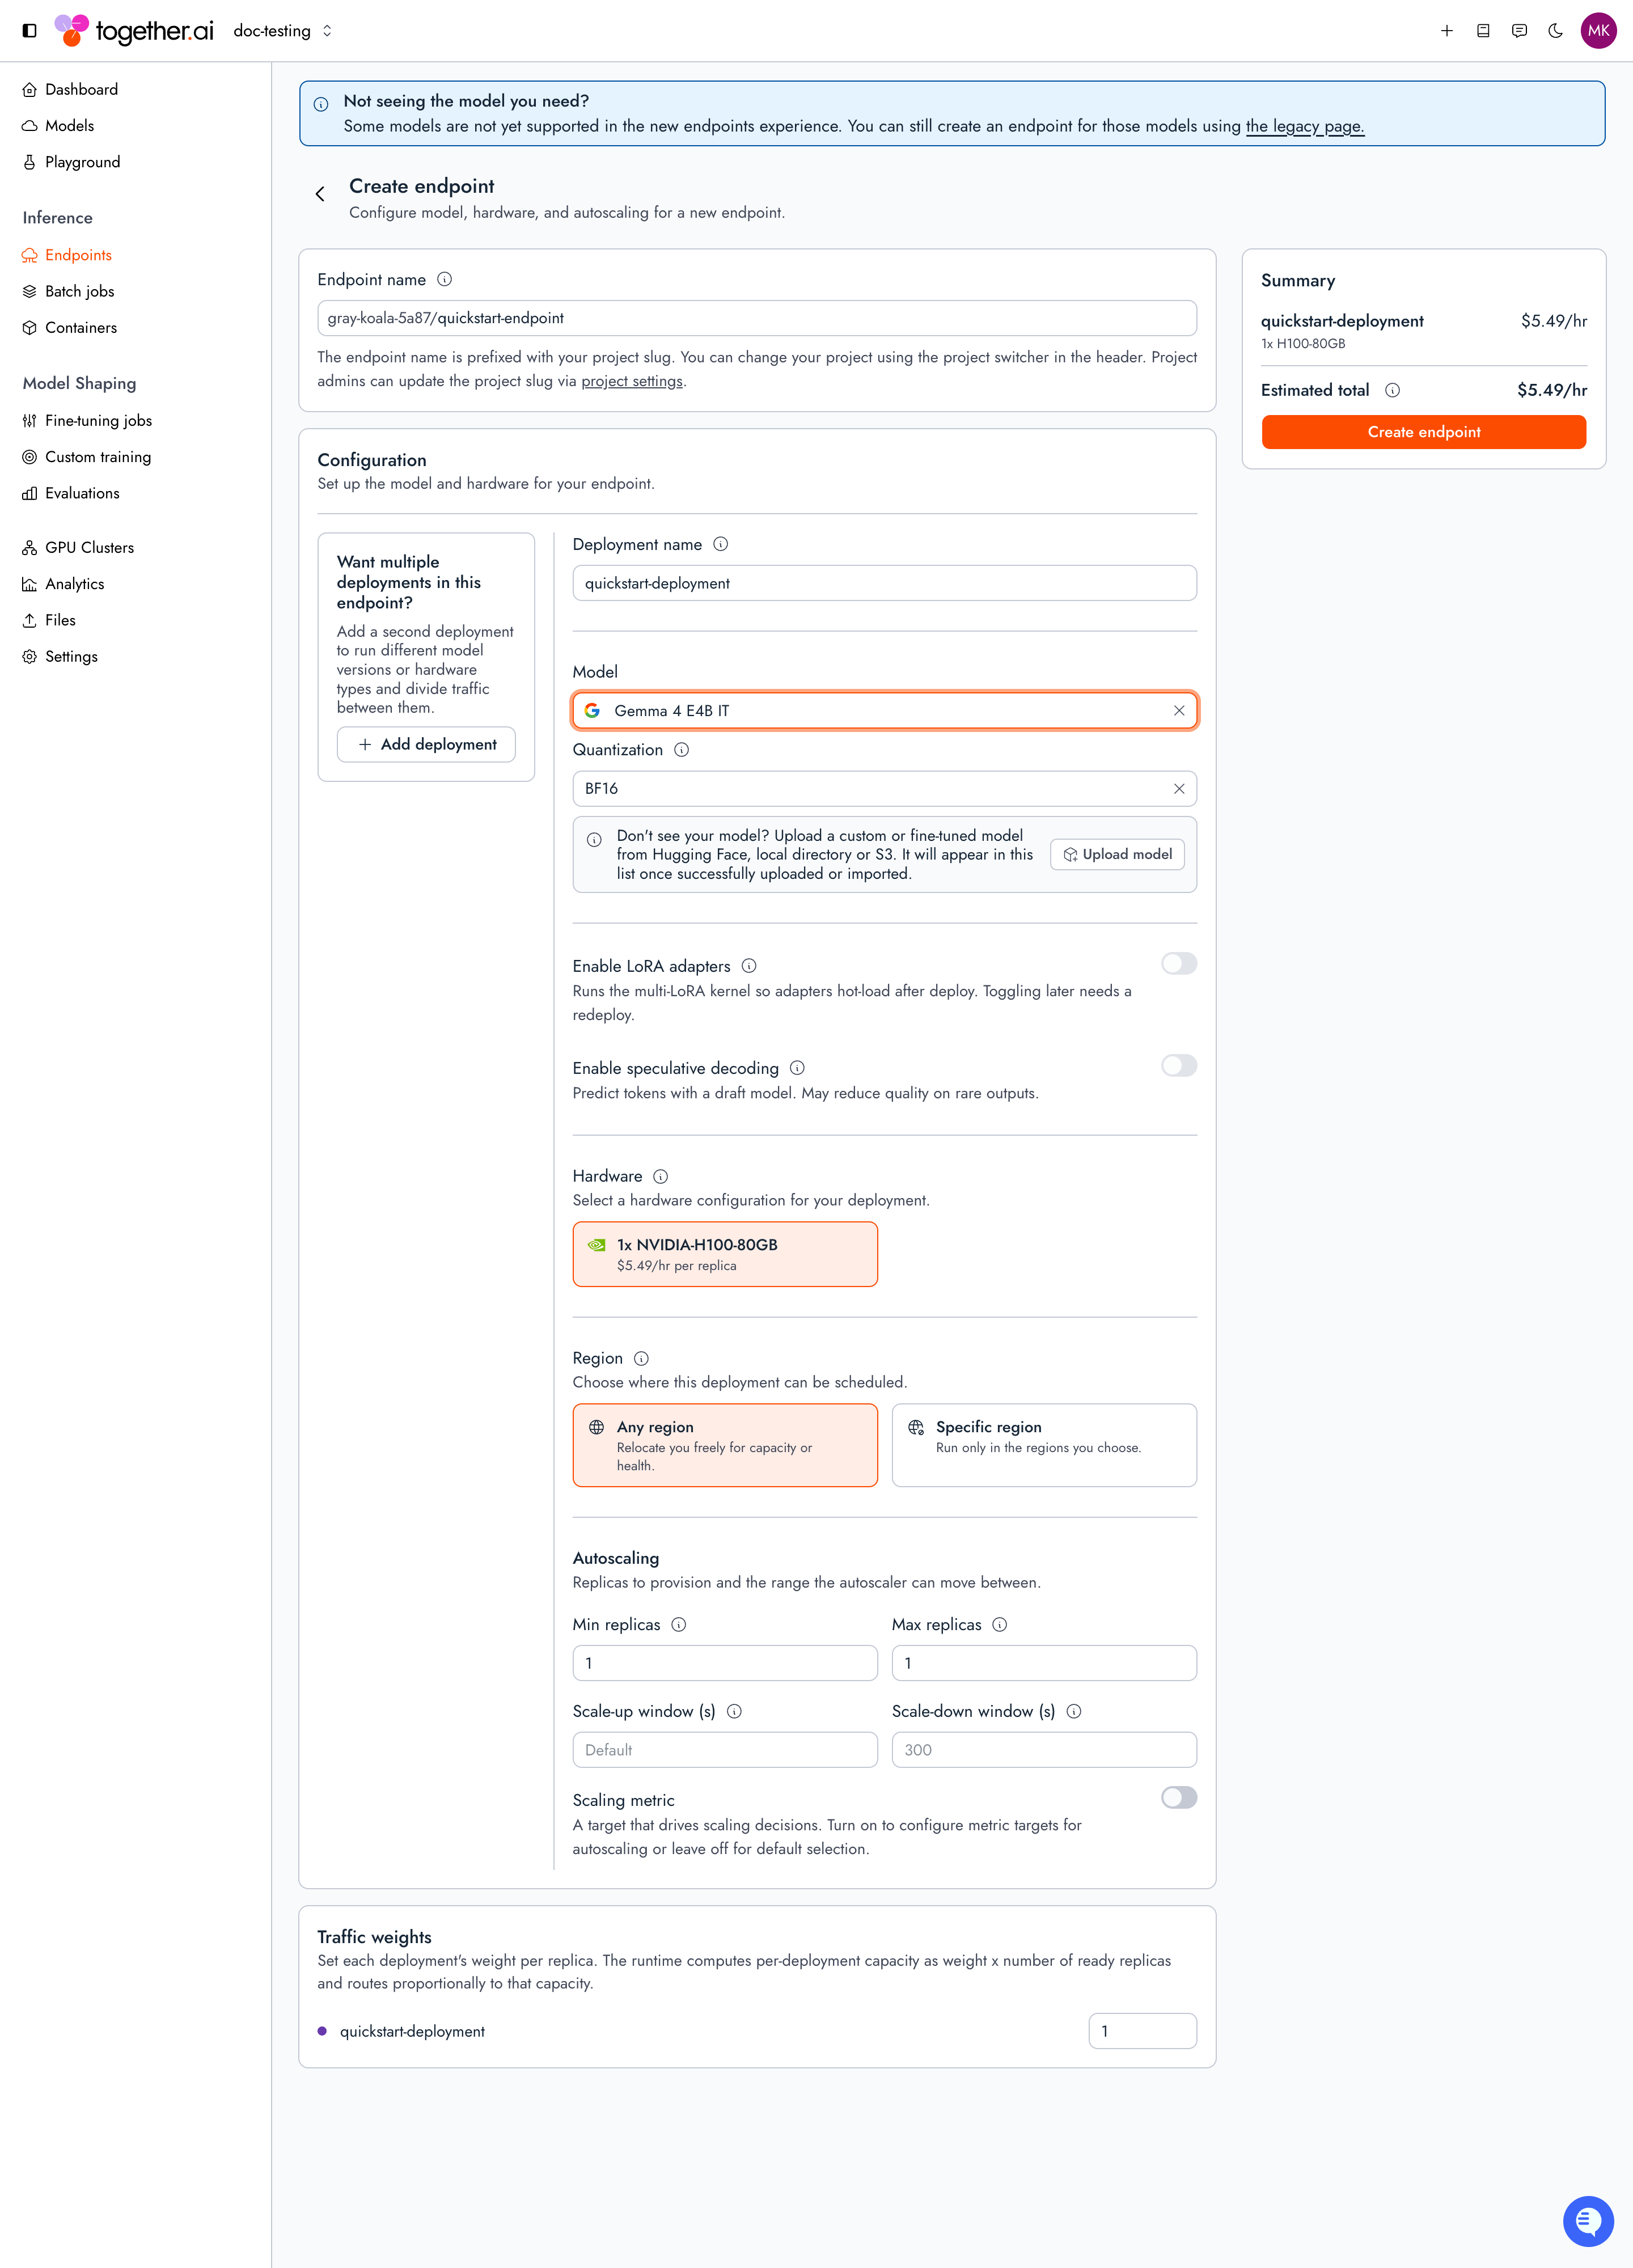
Go to the [Endpoints page](https://api.together.ai/endpoints) and select **New endpoint**.
In **Endpoint name**, enter `quickstart-endpoint`. In **Deployment name**, enter `quickstart-deployment`. The console requires a deployment name, unlike the CLI, which generates one for you.
Under **Model**, select `google/gemma-4-E4B-it`, and leave the default **Quantization**.
Leave the default **Hardware** and **Region**, and keep **Min replicas** and **Max replicas** at `1`.
Select **Create endpoint**. You land on the endpoint's page, where the deployment starts in **Provisioning** and moves to **Ready** once it's live.
Copy the **endpoint string** shown on the endpoint's page (in the form `your-project-slug/quickstart-endpoint`): this is what you pass as the `model` parameter when you send requests.
 ## Step 2: Send a request
Point the inference base URL at `https://api-inference.together.ai/v1`, pass the endpoint string as the `model` parameter, and use the same request shape as a [serverless model](/docs/inference/overview#shared-inference-api):
```python Python theme={null}
from together import Together
client = Together(base_url="https://api-inference.together.ai/v1")
response = client.chat.completions.create(
model="your-project-slug/quickstart-endpoint",
messages=[{"role": "user", "content": "What is 2+2?"}],
max_tokens=512,
)
print(response.choices[0].message.content)
```
```typescript TypeScript theme={null}
import Together from 'together-ai';
const client = new Together({
baseURL: 'https://api-inference.together.ai/v1',
});
const response = await client.chat.completions.create({
model: 'your-project-slug/quickstart-endpoint',
messages: [{ role: 'user', content: 'What is 2+2?' }],
max_tokens: 512,
});
console.log(response.choices[0].message.content);
```
```bash cURL theme={null}
curl -s -X POST https://api-inference.together.ai/v1/chat/completions \
-H "Authorization: Bearer $TOGETHER_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "your-project-slug/quickstart-endpoint",
"messages": [{"role": "user", "content": "What is 2+2?"}],
"max_tokens": 512
}' | jq .
```
You should see output similar to this:
```json theme={null}
{
"id": "8d43d9055fa845b2b1ad11b946191a7e",
"object": "chat.completion",
"created": 1782839730,
"model": "your-project-slug/quickstart-endpoint",
"choices": [
{
"index": 0,
"message": {
"role": "assistant",
"content": "2 + 2 = 4."
},
"finish_reason": "stop"
}
],
"usage": {
"prompt_tokens": 74,
"completion_tokens": 13,
"total_tokens": 87
}
}
```
Congrats! You deployed and called your first dedicated model on Together AI.
## Step 3: Clean up resources
Dedicated model inference bills per minute per running replica, so tear down what you deployed once you're done.
Pass the endpoint ID (`ep_abc123`) from the deploy output to `rm` with `--force` to delete the endpoint and its deployment in one step:
```bash theme={null}
tg beta endpoints rm ep_abc123 --force
```
To stop charges without deleting anything (for example, to redeploy later), [scale the deployment](/docs/dedicated-endpoints/manage#stop-a-deployment) to zero instead, then re-run the status command above to confirm it reaches `DEPLOYMENT_STATE_STOPPED`.
On the endpoint's page, open the deployment and select **Stop** to scale it to zero, which stops the per-minute charges. To bring it back later, select **Start**.
To remove the endpoint entirely, delete it once the deployment is stopped: open **Endpoint actions** and select **Delete endpoint**, then confirm. The console keeps **Delete endpoint** disabled until every deployment under the endpoint is stopped or deleted.
## Next steps
Understand the resource model and development workflow.
Create, scale, stop, and delete endpoints and deployments.
Autoscale a deployment on the metric that fits your workload.
Deploy a model you fine-tuned from a supported base model.