

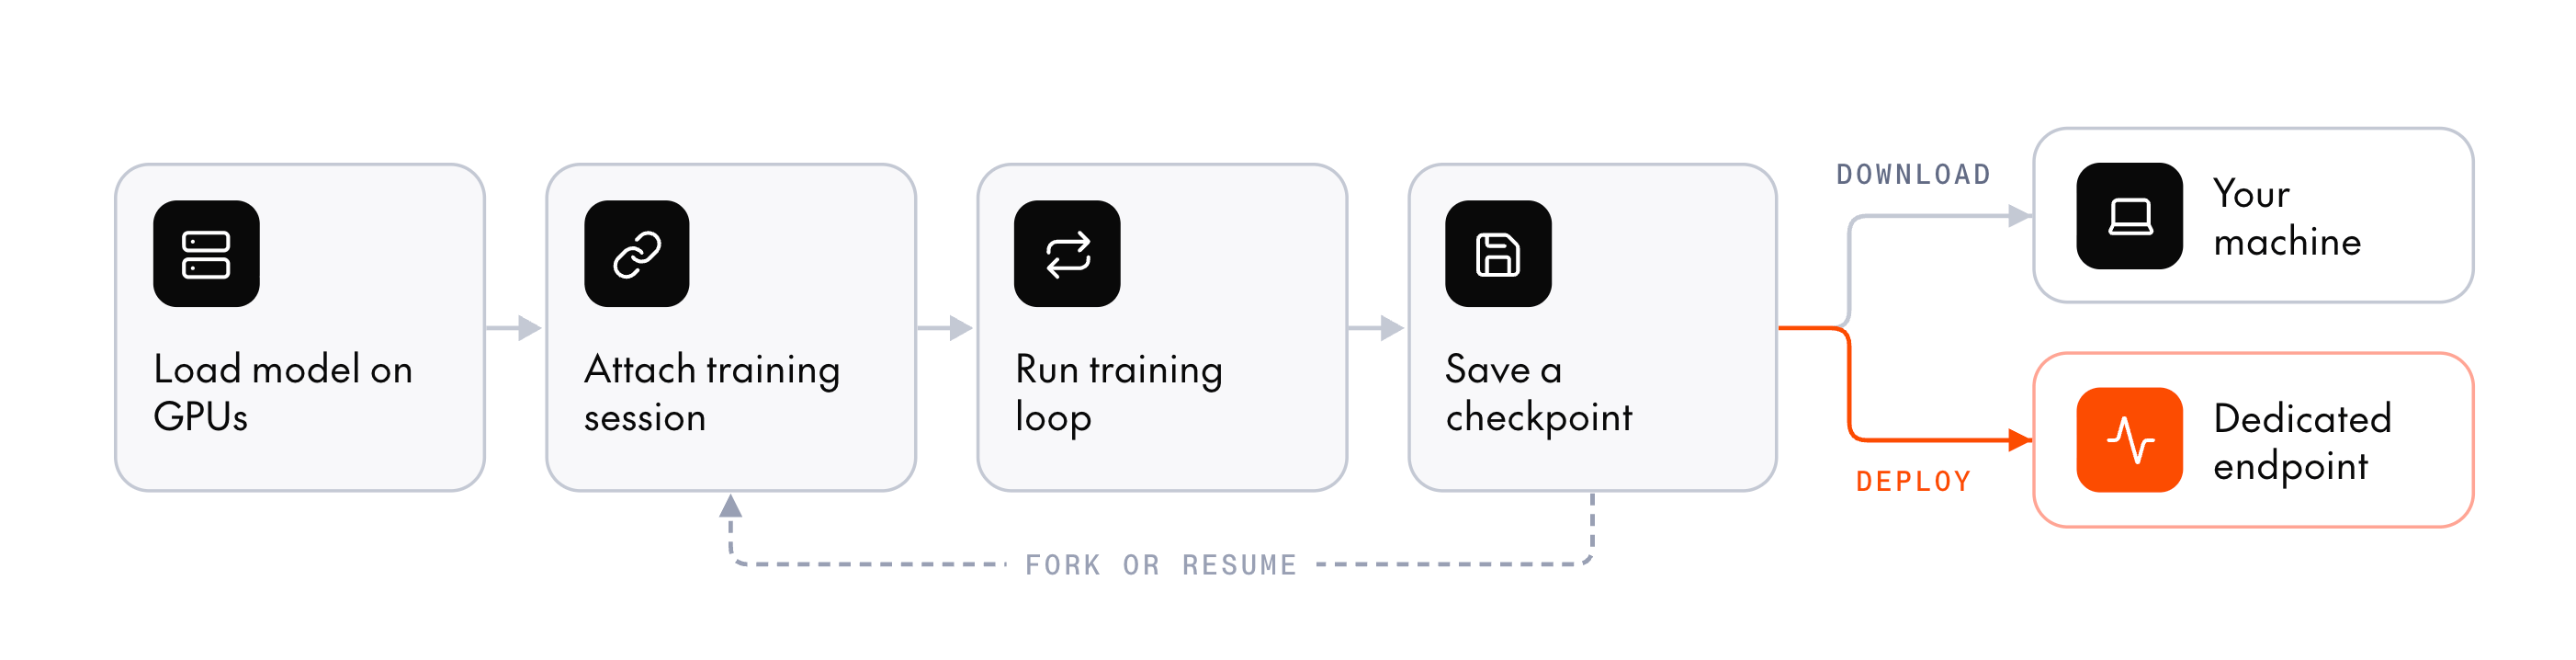
- Supervised fine-tuning (SFT).
- Direct preference optimization (DPO).
- Reinforcement learning with group relative policy optimization (GRPO).
- Multi-turn GRPO.
Key features
- Train on outcomes: With reinforcement learning, your code scores the model’s outputs, so you can train on any task where you can check the answer, even if you can’t provide training examples.
- Train agents: Fine-tune models in multi-turn environments, where the model acts over several turns and can call tools.
- Control every step: Your code chooses each batch, learning rate, and loss function. For any training method, you can write your own loss function that computes the loss in PyTorch from the model’s log-probabilities.
- No infrastructure management: Your loop runs on your laptop, while Together AI runs the sharded trainer, the generator replicas, and the weight sync between them. See Concepts for more details.
- Iterate cheaply, then deploy: Train several low-rank adapters (LoRAs) on one base model while paying for only that base model’s GPU time, then deploy the best one for dedicated model inference.
Get started
SFT quickstart
Run a cookbook SFT recipe that trains a model on instruction-following examples.
GRPO quickstart
Run a cookbook GRPO recipe that trains a model on grade-school math with an exact-match reward.
Write a training loop
Run a minimal training loop with the Python SDK, then add batching and sampling.
Supported models
Pick a base model by training mode, context length, and GPU type.
Migrate from Tinker
Run a Tinker training script by changing its import line.
Cookbook recipes vs. writing your own loop
There are two main ways to use post-training, both of which use the same underlying APIs and infrastructure:- Run a cookbook recipe: Choose this if a ready-made training loop fits your task. The post-training cookbook is a Python library of recipes that handle dataset loading, tokenization, the loop itself, and, for GRPO, reward scoring. You can tune a run by editing its config.
- Write your own loop with the SDK: Choose this if you need more control over data, sampling, rewards, or the loss function.
Post-training vs. standard fine-tuning
Together AI also offers a job-based fine-tuning service for standard workloads. If you only need SFT or DPO, and your data is well formed, it’s much simpler to use: just upload a dataset, submit a job, and wait for the model to train. Post-training is more powerful but more complex. It uses a session-based workflow in which your own code runs the training loop against remote GPUs. The table summarizes the main differences:Train, evaluate, and productionize adapters
A training project usually produces several candidate adapters. Post-training lets you train them on one base model, compare them, and promote the winner: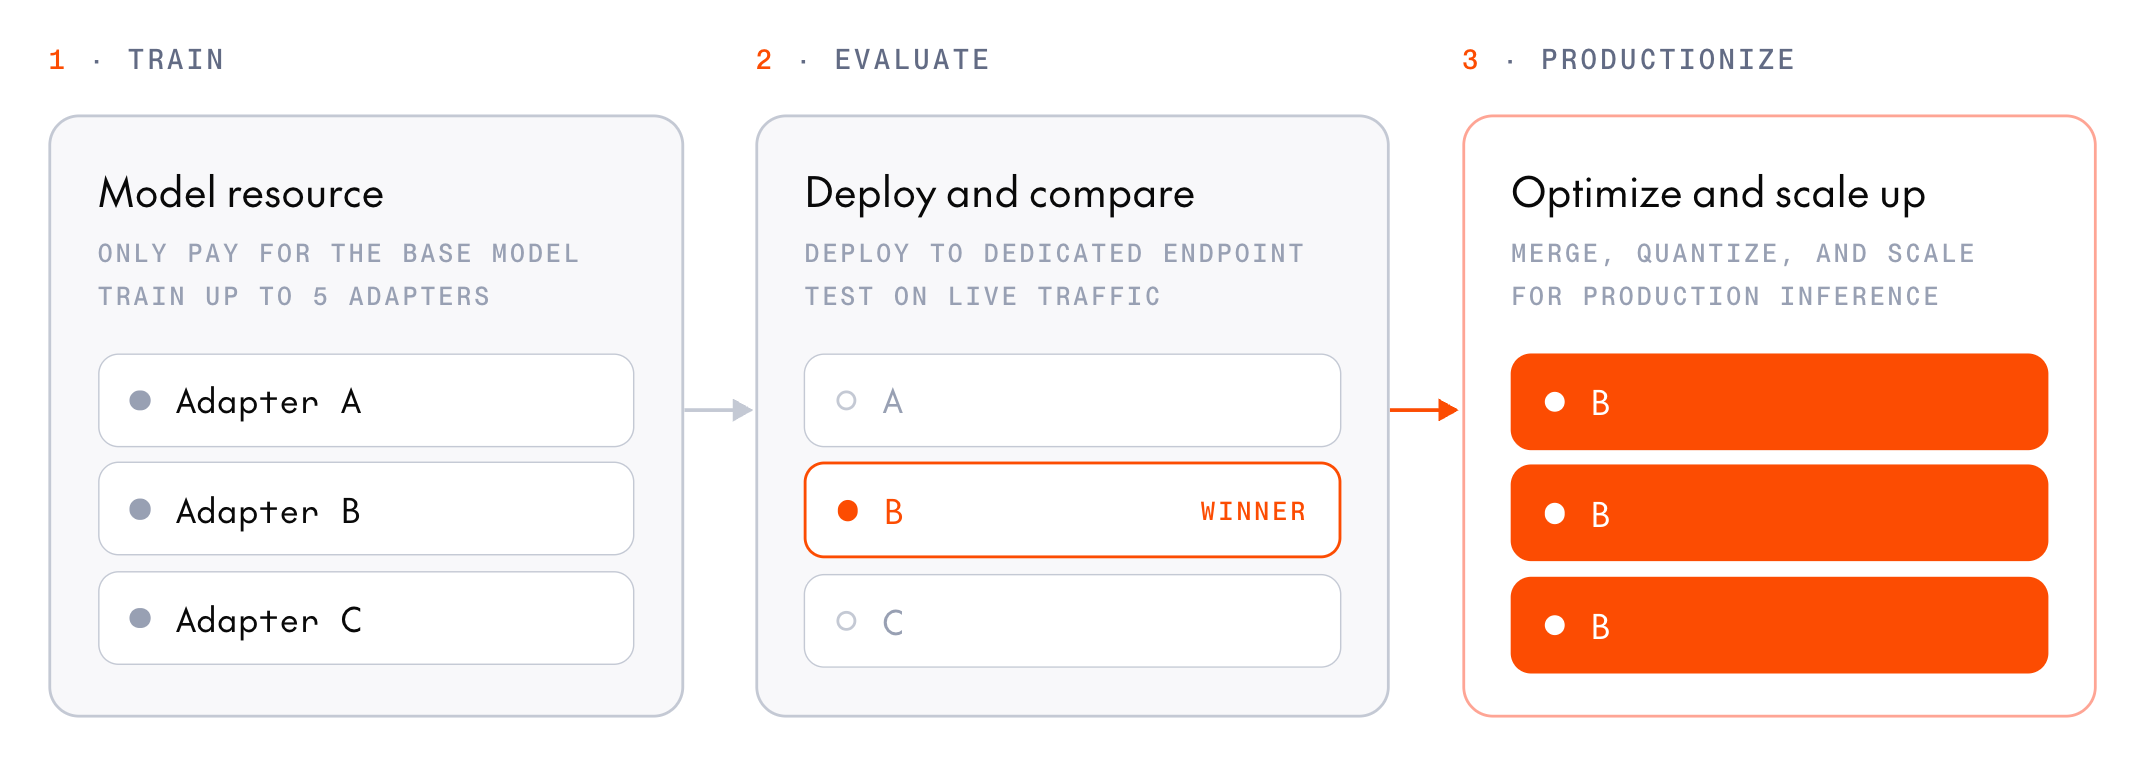
- Train: Attach several training sessions to one model resource. Each session trains an independent adapter against the same frozen base model.
- Evaluate: If the base model supports multi-LoRA deployment, attach the candidates to one deployment of that model on dedicated GPUs, then compare them by naming a different adapter in each request. Each candidate is ready to attach once its session saves an inference checkpoint, which registers the adapter as a model.
- Productionize: Deploy the winner on its own deployment, where each replica merges the adapter into the base model’s weights when it starts. If the base model is served only in FP4, prepare the adapter for FP4 inference instead, then deploy the prepared model.
Learn more
Concepts
Learn how work splits between your code and Together AI GPUs, and what model resources, sessions, and checkpoints do.
Choose a training method
Compare SFT, DPO, and GRPO by the training data each one needs, and combine methods.
Model resources
Size, create, attach to, and stop the GPUs your sessions train on.
Pricing
Learn how per-GPU-minute billing and refunds on failure work, and estimate what a run costs.
Manage checkpoints
Save, download, and resume from what you trained.
Deploy a checkpoint
Serve a trained model on dedicated model inference.