

Lifecycle
MODEL_RESOURCES_STATUS_READY for READY or TRAINING_SESSION_STATUS_RUNNING for RUNNING.
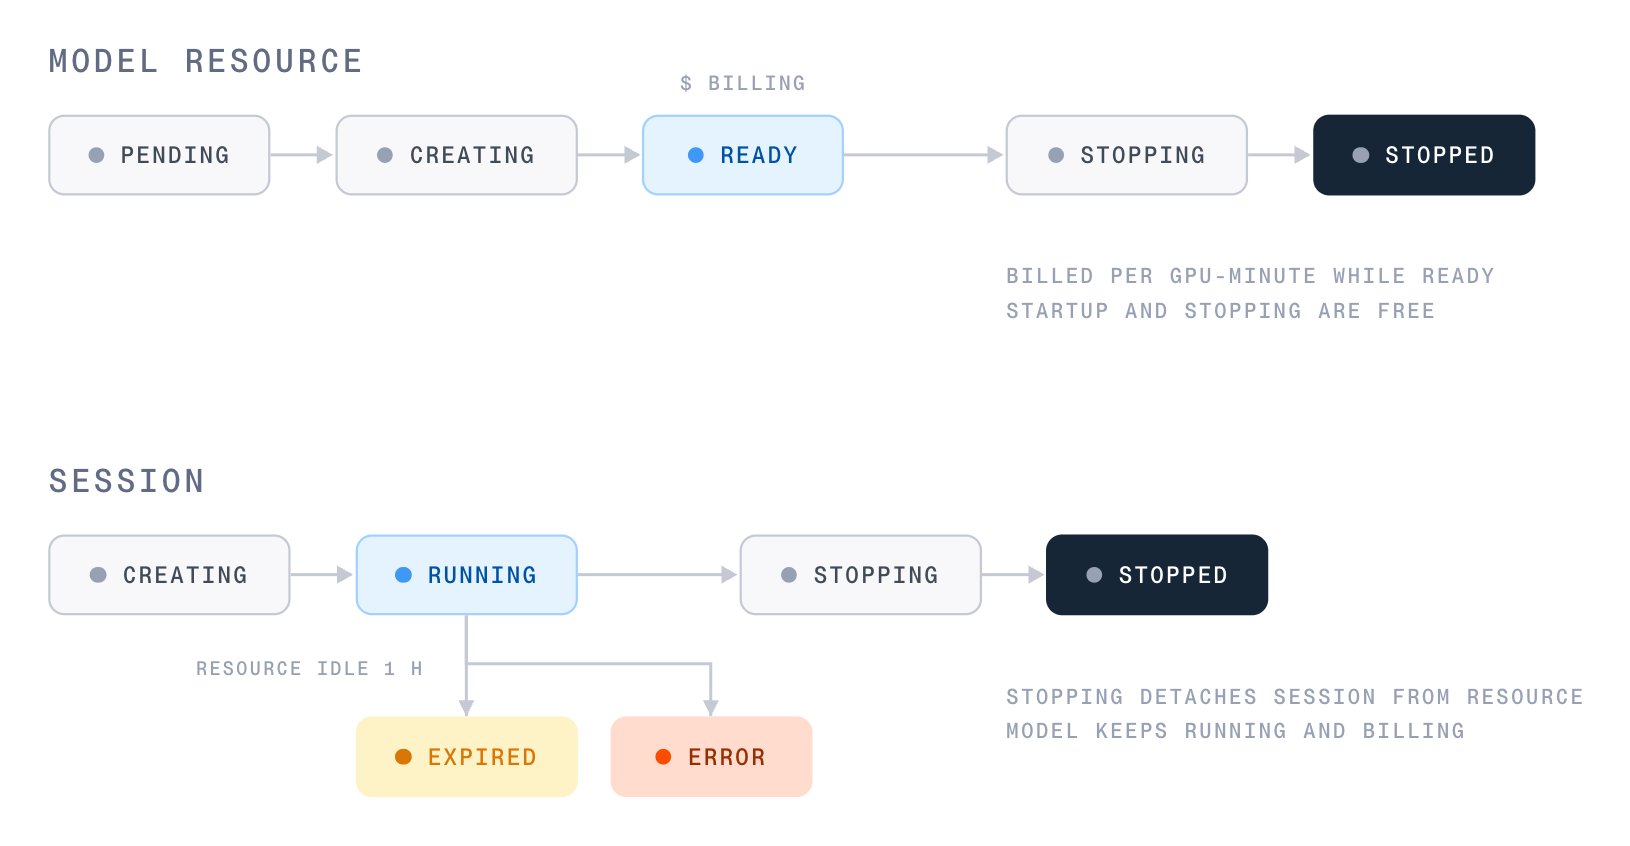
Model resource: PENDING → CREATING → READY → STOPPING → STOPPED, or ERROR.
PENDINGmeans the resource is waiting for GPUs. It first waits in a queue, with no time limit, for a cluster with free capacity for its GPU type. Then it waits for its pods to be scheduled on that cluster. While it’s queued,status_details.queue_positionshows its place in line.CREATINGmeans the pods are scheduled and the base model is loading.READYmeans sessions can attach. Billing runs only in this state.ERRORcan follow any active state.error.codeholds the cause:MODEL_RESOURCES_ERROR_CODE_CAPACITY_WAIT_TIMEOUT: The resource left the queue for a cluster, but its pods weren’t scheduled within an hour. It was never billed.MODEL_RESOURCES_ERROR_CODE_PROVISIONING_FAILED: The resource’s pods were scheduled, but it didn’t finish starting, either because startup failed or because it wasn’tREADYwithin an hour. It was never billed.MODEL_RESOURCES_ERROR_CODE_RESOURCE_UNAVAILABLE: AREADYresource failed, and a trailing window of its runtime is refunded.
CREATING → RUNNING → STOPPING → STOPPED, or EXPIRED or ERROR.
STOPPEDmeans the session was stopped, which only detaches it from the resource. The resource and its other sessions keep running, and billing continues until the resource itself stops.EXPIREDmeans the session’s resource reached its idle timeout (one hour by default) without an operation from any of its sessions, so every session on it was detached. An idle session doesn’t expire while another session on the same resource is still training. The check runs every minute, so sessions expire within about a minute of the timeout.ERRORmeans the session failed to start, to keep running, or to stop. Read the cause fromsession.retrieve().error, which holds acode, amessage, and anoccurred_attimestamp:TRAINING_SESSION_ERROR_CODE_RESOURCE_UNAVAILABLE: The session’s model resource is no longer available, so the session can’t continue.TRAINING_SESSION_ERROR_CODE_RESOURCE_AT_CAPACITY: The session couldn’t start because the resource already hosts as many sessions as it accepts. Stop another session on the resource, or use a different resource.TRAINING_SESSION_ERROR_CODE_TIMED_OUT: The session didn’t become ready in time.TRAINING_SESSION_ERROR_CODE_SESSION_FAILED: The session failed for any other reason.
STOPPING, STOPPED, EXPIRED, or ERROR instead of RUNNING, create_session raises RuntimeError with the session ID and that status. You don’t get a session handle in that case, so read the error by ID with client.post_training.sessions.retrieve("your_session_id").error. To continue training after a session error, create a new session, resuming from a training checkpoint if you saved one.
Timers
On long runs, save training checkpoints so that an expiry or unexpected stop loses only the work since your last checkpoint.
Operation errors
When an operation such asforward_backward, optim_step, or sample fails on the model resource, the SDK raises OperationFailedError. The together.post_training module doesn’t export that class, so catch its parent class, RuntimeError. The exception message holds the operation ID and the operation’s error, which has a code and a message that says what went wrong:
TRAINING_OPERATION_STATUS_FAILED and the same error.
If the session had already left
RUNNING when you submitted the operation, the API rejects the request without creating an operation. It returns HTTP 400 with training session is not running (current status: ...), which the SDK raises as BadRequestError. Handle it the same way as SESSION_NOT_ACTIVE.
Limits
Creating a resource also needs enough credit to run it for four hours.
Rate limits
Rate limits apply per project or per session, depending on the call. A burst is how many calls can go through at once before the rate applies. When you exceed a limit, the API returns HTTP429.
The SDK retries any request that fails with a connection error or an HTTP
408, 409, 429, or 5xx response. It retries session calls, which include every operation, up to seven times. If a call still gets a 429 after the last retry, the SDK raises RateLimitError. Each operation carries an idempotency key, so a retried submission doesn’t create a second operation. Don’t wrap operation calls in your own retry loop.
Troubleshooting
- The resource stays
PENDINGfor a long time: No B200 GPU capacity is free yet. The resource stays in the queue until GPUs free up or you stop it, and you aren’t billed while it waits. Checkstatus_details.queue_positionto see its place in line. createraisesTimeoutErrorwhile the resource is stillPENDING: Theready_timeoutyou passed ran out before the resource left the queue, so the SDK stopped the resource. To wait longer, create the resource again with a largerready_timeout, or leave it unset to wait until the resource gets GPUs. The new resource joins the back of the queue, so when capacity is scarce, leaveready_timeoutunset from the start.- Create is rejected with
rate limit exceeded, retry after ...: Your project has reached its create rate limit. The API returns HTTP429, which the SDK raises asRateLimitErrorafter retrying. Wait for the time in the message, then retry. To stay under the limit, reuse a running resource by attaching sessions to it instead of creating one for each run. - Create is rejected with
organization GPU quota exceeded: Your organization has a quota on the total GPUs that itsPENDING,CREATING, andREADYresources hold, and the new resource would exceed it. The API returns HTTP403, which the SDK raises asPermissionDeniedError, with a message such asorganization GPU quota exceeded: 112 of 120 GPUs in use, requested 16. Stop resources you no longer need, or contact support to request a higher quota. - Create fails for the GPU type, training mode, or generator replicas: The model doesn’t support that combination. Check the model’s row on Supported models.
- Create is rejected with
project balance cannot cover 4 hours of this model resource: The API returns HTTP402(insufficient_balance) when your project’s balance plus its credit limit can’t cover four hours of the resource at its hourly rate, or when the project is already past its credit limit. Add credits and retry, or lower the hourly rate with fewer generator replicas, LoRA instead of full-weight training, or a smaller base model. stopis refused because a session is still active: Stop the sessions first, or passforce=True. The context-manager exit on an owned resource doesn’t force, so it fails the same way if a session you don’t own is still attached.- An operation call raises
TimeoutError: The call’stimeout, 300 seconds by default or 7200 seconds for checkpoint saves, ran out before the operation finished. The SDK stopped waiting, but the operation keeps running on the service, and there’s no call to cancel it. Don’t resubmit it, because a secondforward_backwardis a new operation whose gradients add to the first one’s. For slow steps on large models or large batches, pass a largertimeout, ortimeout=Noneto wait indefinitely. - An operation raises
OperationFailedError: Operation (...) failed: Look up thecodefrom the message in Operation errors. - An operation fails with
SESSION_NOT_ACTIVEortraining session is not running: The session was stopped, expired when its resource reached its idle timeout, or hit an error. Readsession.retrieve().statusandsession.retrieve().error, then create a new session, resuming from a training checkpoint if you saved one. - A running resource stopped on its own: The billing system reported that your project’s credit limit was exceeded or your organization was blocked, or the resource reached its idle timeout (one hour by default) without an operation from any session. Check your available credit and account status, then check the session statuses for
EXPIRED. If neither explains the stop, contact support with the resource ID and the time it stopped. To continue training, resume from your last training checkpoint.